Show Code
import math
import torch
from torch import nnWe will build a toy GPT archeticture introduced in the paper GPT — Radford et al. (2018). Training it on Atabic dataset from wikipedia.
import math
import torch
from torch import nnfrom data_pipeline import train_loader, tokenizer, SEQ_LEN, BATCH_SIZE
VOCAB_SIZE = tokenizer.get_vocab_size()
print(f"vocab size : {VOCAB_SIZE:,}")
print(f"seq_len : {SEQ_LEN}")
print(f"batch_size : {BATCH_SIZE}")
print(f"train blocks : {len(train_loader.dataset):,}")vocab size : 8,000
seq_len : 128
batch_size : 32
train blocks : 52,076x_batch, y_batch = next(iter(train_loader))
print("x_batch shape:", x_batch.shape)
print("y_batch shape:", y_batch.shape)
print("\nx_batch[0][:10]:", x_batch[0][:10].tolist())
print("y_batch[0][:10]:", y_batch[0][:10].tolist())
# sanity check: y is x shifted by one position, so x[1:] should equal y[:-1]
print("\nshift check (should be True):",
torch.equal(x_batch[0][1:], y_batch[0][:-1]))
print("\ndecoded x[0]:", tokenizer.decode(x_batch[0].tolist()))x_batch shape: torch.Size([32, 128])
y_batch shape: torch.Size([32, 128])
x_batch[0][:10]: [296, 476, 329, 7355, 840, 308, 522, 570, 315, 387]
y_batch[0][:10]: [476, 329, 7355, 840, 308, 522, 570, 315, 387, 776]
shift check (should be True): True
decoded x[0]: ين كان قليلا ولكن كثر العالمون بالآداب اليونانية الكلاسيكية والنقاد وعلماء اللغة وبرز شعراء مسرحيات. لعل أجمل ما كتب الشعر الديني. كل ما يسمى في الصلوات القنداق والقانون شعر. إلى هذا عرفت بيزنطية الشعر الشعبي والقصة بالفصحى وبالعامية.
العلوم والطب
كذلك عرفت الحضارة البيزنطية الأرثوذكسية علماء رياضيات وفيزياء وبصريات. عرف البيزنطيون علم الحيوان من الناحية التطبيقية وعلم النبات التطبيقي أي استعمال النبات في الطب والصيدلة. أخذوا الخيمياء عن سترابون وطبقوها في المعادن والصبThe GPT-1 is a decoder only block with a multi-head self-attention, layer normalization, and feed-forward neural network. This is for a single GPT block (1 layer). The full GPT model consists of multiple such blocks stacked together.
class MultiHeadAttention(nn.Module):
    def __init__(self, d_model, num_heads):
        super().__init__()

        assert d_model % num_heads == 0, "d_model must be divisible by num_heads"
        self.num_heads = num_heads
        self.d_k = d_model // num_heads

        self.W_Q = nn.ModuleList([nn.Linear(self.d_k, self.d_k)
                                 for _ in range(num_heads)])
        self.W_K = nn.ModuleList([nn.Linear(self.d_k, self.d_k)
                                 for _ in range(num_heads)])
        self.W_V = nn.ModuleList([nn.Linear(self.d_k, self.d_k)
                                 for _ in range(num_heads)])

        # The weights to the ouptut, need to combine the result of the heads above before calling this.
        self.W_O = nn.Linear(d_model, d_model)

    def forward(self, query_input, kv_input=None, mask=None):

        if kv_input is None:
            kv_input = query_input   # plain self-attention: Q, K, V all from the same source

        # split the input into per-head chuncks
        query_chunks = query_input.split(self.d_k, dim=-1)
        kv_chunks = kv_input.split(self.d_k, dim=-1)

        head_outputs = []
        head_weights = []

        for i in range(self.num_heads):
            Q = self.W_Q[i](query_chunks[i])
            K = self.W_K[i](kv_chunks[i])
            V = self.W_V[i](kv_chunks[i])

            scores = Q @ K.transpose(-2, -1) / math.sqrt(self.d_k)
            # adding the mask padding (zero out scores for padding tokens)
            if mask is not None:
                if mask.dim() == 2:
                    # (batch, seq_k) -> (batch, 1, seq_k), broadcasts across all queries
                    mask = mask.unsqueeze(1)
                scores = scores.masked_fill(mask, float('-inf'))

            attention_weights = torch.softmax(scores, dim=-1)
            output = torch.matmul(attention_weights, V)

            # Store each head outputs and weights
            head_outputs.append(output)
            head_weights.append(attention_weights)

        # concatenate all heads outputs
        concat = torch.cat(head_outputs, dim=-1)   # (batch, seq_len, d_model)

        # Project the concatenated outputs to a d_model learnable
        output = self.W_O(concat)   # (batch, seq_len, d_model)

        # stack the attention weights (batch, num_heads, seq_len, seq_len)
        attention_weights = torch.stack(head_weights, dim=1)

        return output, attention_weights
The causal mask blocks every query position from attending to any future key position, forcing predictions to depend only on what came before.
class GPTBlock(nn.Module):
    def __init__(self, d_model, num_heads, ff_hidden):
        super().__init__()

        self.multi_head_atten = MultiHeadAttention(d_model, num_heads)
        # Layer normalize
        self.norm1 = nn.LayerNorm(d_model)
        # feed forward net
        self.ff = nn.Sequential(
            nn.Linear(d_model, ff_hidden),
            nn.ReLU(),
            nn.Linear(ff_hidden, d_model)
        )

        # Layer normalization after feed-forward
        self.norm2 = nn.LayerNorm(d_model)

        #Define a drop out layer
        self.dropout = nn.Dropout(0.1)


    def forward(self, x, mask):
        attention_output, attention_weights = self.multi_head_atten(x, mask=mask)

        x = self.norm1(x + self.dropout(attention_output))

        ff_output = self.ff(x)

        x = self.norm2(x + self.dropout(ff_output))

        return x, attention_weights
class PositionalEncoding(nn.Module):
    def __init__(self, d_model, max_len=100):
        super().__init__()
        pe = torch.zeros(max_len, d_model)
        position = torch.arange(0, max_len).unsqueeze(1)
        div_term = torch.exp(torch.arange(0, d_model, 2)
                             * (-math.log(10000.0) / d_model))
        pe[:, 0::2] = torch.sin(position * div_term)
        pe[:, 1::2] = torch.cos(position * div_term)
        # fixed, not learned — moves with .to(device) but isn't a Parameter
        self.register_buffer("pe", pe)

    def forward(self, x):
        # x: (batch, seq_len, d_model)
return x + self.pe[:x.size(1)]class GPT(nn.Module):
def __init__(self, d_model, ff_hidden, num_heads, num_layers):
super().__init__()
self.embedding = nn.Embedding(VOCAB_SIZE, d_model)
self.positional_encoding = PositionalEncoding(d_model, max_len=SEQ_LEN)
self.layers = nn.ModuleList([GPTBlock(d_model, num_heads, ff_hidden) for _ in range(num_layers)])
self.dropout = nn.Dropout(0.1)
self.output_layer = nn.Linear(d_model, VOCAB_SIZE)
def forward(self, token_ids):
seq_len = token_ids.size(1)
causal_mask = torch.triu(
torch.ones(seq_len, seq_len, dtype=torch.bool, device=token_ids.device), diagonal=1
).unsqueeze(0)
x = self.embedding(token_ids)
x = self.positional_encoding(x)
x = self.dropout(x)
for layer in self.layers:
x, attention_weights = layer(x, mask=causal_mask)
logits = self.output_layer(x)
return logits, attention_weightsclass NoamScheduler:
def __init__(self, optimizer, d_model, warmup_steps=400):
self.optimizer = optimizer
self.d_model = d_model
self.warmup_steps = warmup_steps
self.step_num = 0
def step(self):
self.step_num += 1
lr = (self.d_model ** -0.5) * min(self.step_num ** -
0.5, self.step_num * self.warmup_steps ** -1.5)
for group in self.optimizer.param_groups:
group['lr'] = lr
self.optimizer.step()device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
model = GPT(d_model=128, ff_hidden=512, num_heads=4, num_layers=4).to(device)
optimizer = torch.optim.Adam(
model.parameters(), lr=0, betas=(0.9, 0.98), eps=1e-9)
scheduler = NoamScheduler(optimizer, d_model=128, warmup_steps=1000)
# no ignore_index needed — no padding anywhere in this dataset
loss_fn = nn.CrossEntropyLoss()
num_epochs = 3
loss_history = []
for epoch in range(num_epochs):
model.train()
total_loss, num_batches = 0.0, 0
for batch_idx, (x_batch, y_batch) in enumerate(train_loader):
x_batch = x_batch.to(device)
y_batch = y_batch.to(device)
logits, _ = model(x_batch) # (batch, seq_len, vocab_size)
loss = loss_fn(
logits.reshape(-1, VOCAB_SIZE), # (batch*seq_len, vocab_size)
y_batch.reshape(-1) # (batch*seq_len,)
)
optimizer.zero_grad()
loss.backward()
scheduler.step()
loss_history.append(loss.item())
total_loss += loss.item()
num_batches += 1
if batch_idx % 200 == 0:
print(
f"epoch {epoch+1} batch {batch_idx:5d}/{len(train_loader)} loss {loss.item():.4f}")
print(
f"=== epoch {epoch+1:3d} done — avg loss {total_loss/num_batches:.4f} ===")epoch 1 batch 0/1628 loss 9.1670
epoch 1 batch 200/1628 loss 7.5813
epoch 1 batch 400/1628 loss 7.0000
epoch 1 batch 600/1628 loss 6.3699
epoch 1 batch 800/1628 loss 6.1087
epoch 1 batch 1000/1628 loss 5.8675
epoch 1 batch 1200/1628 loss 5.9037
epoch 1 batch 1400/1628 loss 5.7191
epoch 1 batch 1600/1628 loss 5.6447
=== epoch 1 done — avg loss 6.4440 ===
epoch 2 batch 0/1628 loss 5.4355
epoch 2 batch 200/1628 loss 5.3341
epoch 2 batch 400/1628 loss 5.6245
epoch 2 batch 600/1628 loss 5.4686
epoch 2 batch 800/1628 loss 5.5281
epoch 2 batch 1000/1628 loss 5.3470
epoch 2 batch 1200/1628 loss 5.3880
epoch 2 batch 1400/1628 loss 5.2699
epoch 2 batch 1600/1628 loss 5.3454
=== epoch 2 done — avg loss 5.4381 ===
epoch 3 batch 0/1628 loss 5.2974
epoch 3 batch 200/1628 loss 5.3071
epoch 3 batch 400/1628 loss 5.3300
epoch 3 batch 600/1628 loss 5.3349
epoch 3 batch 800/1628 loss 4.9970
epoch 3 batch 1000/1628 loss 5.3013
epoch 3 batch 1200/1628 loss 5.2930
epoch 3 batch 1400/1628 loss 4.9444
epoch 3 batch 1600/1628 loss 5.0925
=== epoch 3 done — avg loss 5.2353 ===
epoch 4 batch 0/1628 loss 5.1558
epoch 4 batch 200/1628 loss 4.8328
epoch 4 batch 400/1628 loss 5.1915
epoch 4 batch 600/1628 loss 5.0524
epoch 4 batch 800/1628 loss 5.1462
epoch 4 batch 1000/1628 loss 5.1687
epoch 4 batch 1200/1628 loss 4.9825
epoch 4 batch 1400/1628 loss 5.1591
epoch 4 batch 1600/1628 loss 5.0778
=== epoch 4 done — avg loss 5.1244 ===
epoch 5 batch 0/1628 loss 4.8434
epoch 5 batch 200/1628 loss 4.9952
epoch 5 batch 400/1628 loss 5.0997
epoch 5 batch 600/1628 loss 5.1998
epoch 5 batch 800/1628 loss 5.0375--------------------------------------------------------------------------- KeyboardInterrupt Traceback (most recent call last) Cell In[23], line 22 19 x_batch = x_batch.to(device) 20 y_batch = y_batch.to(device) ---> 22 logits, _ = model(x_batch) # (batch, seq_len, vocab_size) 24 loss = loss_fn( 25 logits.reshape(-1, VOCAB_SIZE), # (batch*seq_len, vocab_size) 26 y_batch.reshape(-1) # (batch*seq_len,) 27 ) 29 optimizer.zero_grad() File c:\Users\user\Documents\GitHub\simpe-AI\venv\Lib\site-packages\torch\nn\modules\module.py:1775, in Module._wrapped_call_impl(self, *args, **kwargs) 1773 return self._compiled_call_impl(*args, **kwargs) # type: ignore[misc] 1774 else: -> 1775 return self._call_impl(*args, **kwargs) File c:\Users\user\Documents\GitHub\simpe-AI\venv\Lib\site-packages\torch\nn\modules\module.py:1786, in Module._call_impl(self, *args, **kwargs) 1781 # If we don't have any hooks, we want to skip the rest of the logic in 1782 # this function, and just call forward. 1783 if not (self._backward_hooks or self._backward_pre_hooks or self._forward_hooks or self._forward_pre_hooks 1784 or _global_backward_pre_hooks or _global_backward_hooks 1785 or _global_forward_hooks or _global_forward_pre_hooks): -> 1786 return forward_call(*args, **kwargs) 1788 result = None 1789 called_always_called_hooks = set() Cell In[20], line 27, in GPT.forward(self, token_ids) 24 for layer in self.layers: 25 x, attention_weights = layer(x, mask=causal_mask) ---> 27 logits = self.output_layer(x) 30 return logits, attention_weights File c:\Users\user\Documents\GitHub\simpe-AI\venv\Lib\site-packages\torch\nn\modules\module.py:1775, in Module._wrapped_call_impl(self, *args, **kwargs) 1773 return self._compiled_call_impl(*args, **kwargs) # type: ignore[misc] 1774 else: -> 1775 return self._call_impl(*args, **kwargs) File c:\Users\user\Documents\GitHub\simpe-AI\venv\Lib\site-packages\torch\nn\modules\module.py:1786, in Module._call_impl(self, *args, **kwargs) 1781 # If we don't have any hooks, we want to skip the rest of the logic in 1782 # this function, and just call forward. 1783 if not (self._backward_hooks or self._backward_pre_hooks or self._forward_hooks or self._forward_pre_hooks 1784 or _global_backward_pre_hooks or _global_backward_hooks 1785 or _global_forward_hooks or _global_forward_pre_hooks): -> 1786 return forward_call(*args, **kwargs) 1788 result = None 1789 called_always_called_hooks = set() File c:\Users\user\Documents\GitHub\simpe-AI\venv\Lib\site-packages\torch\nn\modules\linear.py:134, in Linear.forward(self, input) 130 def forward(self, input: Tensor) -> Tensor: 131 """ 132 Runs the forward pass. 133 """ --> 134 return F.linear(input, self.weight, self.bias) KeyboardInterrupt:
import matplotlib.pyplot as plt

plt.figure(figsize=(10, 4))
plt.plot(loss_history)
plt.xlabel("training step")
plt.ylabel("loss")
plt.title("GPT training loss")
plt.show()
--------------------------------------------------------------------------- NameError Traceback (most recent call last) Cell In[39], line 4 1 import matplotlib.pyplot as plt 3 plt.figure(figsize=(10, 4)) ----> 4 plt.plot(loss_history) 5 plt.xlabel("training step") 6 plt.ylabel("loss") NameError: name 'loss_history' is not defined
<Figure size 1000x400 with 0 Axes>def generate(prompt, model, max_new_tokens=40, temperature=0.6, device=device):
model.eval()
with torch.no_grad():
ids = tokenizer.encode(prompt).ids
x = torch.tensor([ids], dtype=torch.long, device=device)
for _ in range(max_new_tokens):
logits, _ = model(x)
next_logits = logits[0, -1, :] / temperature
probs = torch.softmax(next_logits, dim=-1)
next_token = torch.multinomial(probs, num_samples=1).item()
x = torch.cat(
[x, torch.tensor([[next_token]], device=device)], dim=1)
return tokenizer.decode(x[0].tolist())
# lower = more conservative/confident
print(generate("العلم هو", model, temperature=0.3))
# higher = more random/diverse
print(generate("العلم هو", model, temperature=0.6))العلم هو الذي يُعرف في ذلك الوقت نفسه، وهو في هذا اليوم، وهو ما يُعرف بِنُقُلُلْرُوْرَلْرِي
العلم هو من الأم، وهو ما يزال يُطلق على ذلك أن يكون أحدًا منه يُعرف معادلات البُويهيين في بعض الأحيان.
قُُمّرَمdef plot_attention(prompt, model, head=0, device=device):
model.eval()
with torch.no_grad():
ids = tokenizer.encode(prompt).ids
x = torch.tensor([ids], dtype=torch.long, device=device)
# (1, num_heads, seq_len, seq_len) — last layer only
_, attention_weights = model(x)
weights = attention_weights[0, head].cpu().numpy()
tokens = [tokenizer.decode([i]) for i in ids]
plt.figure(figsize=(8, 8))
plt.imshow(weights, cmap="viridis")
plt.xticks(range(len(tokens)), tokens, rotation=90)
plt.yticks(range(len(tokens)), tokens)
plt.xlabel("key position (attending TO)")
plt.ylabel("query position (attending FROM)")
plt.title(f"GPT self-attention — head {head}, last layer")
plt.colorbar()
plt.show()
# short prompt — long ones make the grid unreadable
plot_attention("العلم هو نور يضيء الطريق", model, head=0)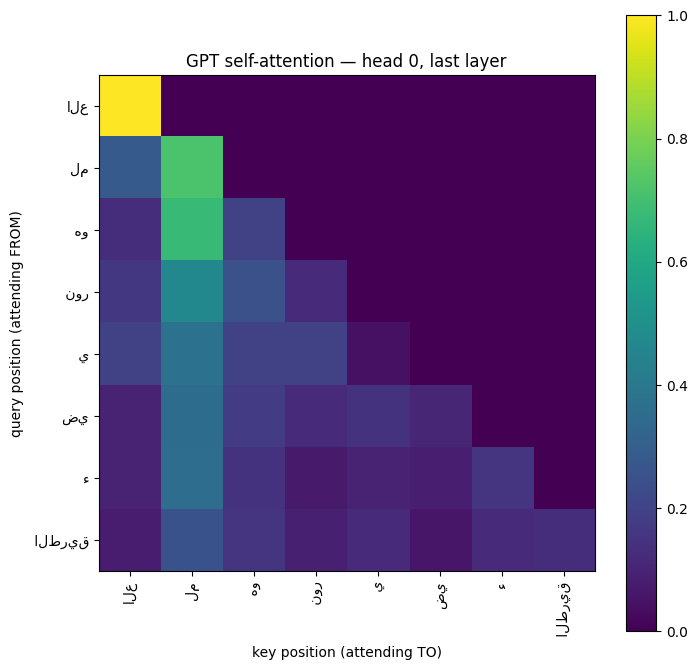
encoding = tokenizer.encode("العلم هو نور يضيء الطريق")
for token_id, piece in zip(encoding.ids, encoding.tokens):
    print(token_id, repr(piece))
2065 'اÙĦع'
380 'ÙĦÙħ'
563 'ĠÙĩÙĪ'
2769 'ĠÙĨÙĪر'
309 'ĠÙĬ'
2511 'ضÙĬ'
614 'Ø¡'
3099 'ĠاÙĦطرÙĬÙĤ'
Comments